Fewer Inodes Do Not Guarantee Reduced Disk Consumption
When engineering leads compared the final client delivery snapshot against the milestone checkpoint recorded three weeks earlier, the directory counters showed an apparent operational success: total file count dropped from 61,540 down to 19,422. Most teams assume that eliminating more than forty-two thousand files inevitably frees disk capacity. However, the volume allocation charts told the opposite story, displaying an immediate jump from 312.4 GB to 497.0 GB across the project branch.
Standard project reporting utilities often obscure capacity realities because they focus on file system inodes rather than block allocations. The consolidation of multiple development dependencies into monoliths commonly disguises runaway storage growth. In this specific delivery pipeline, active project cleanup eliminated transient development directories, yet automated packaging scripts simultaneously generated colossal, uncompressed binary aggregates right inside the release tree.
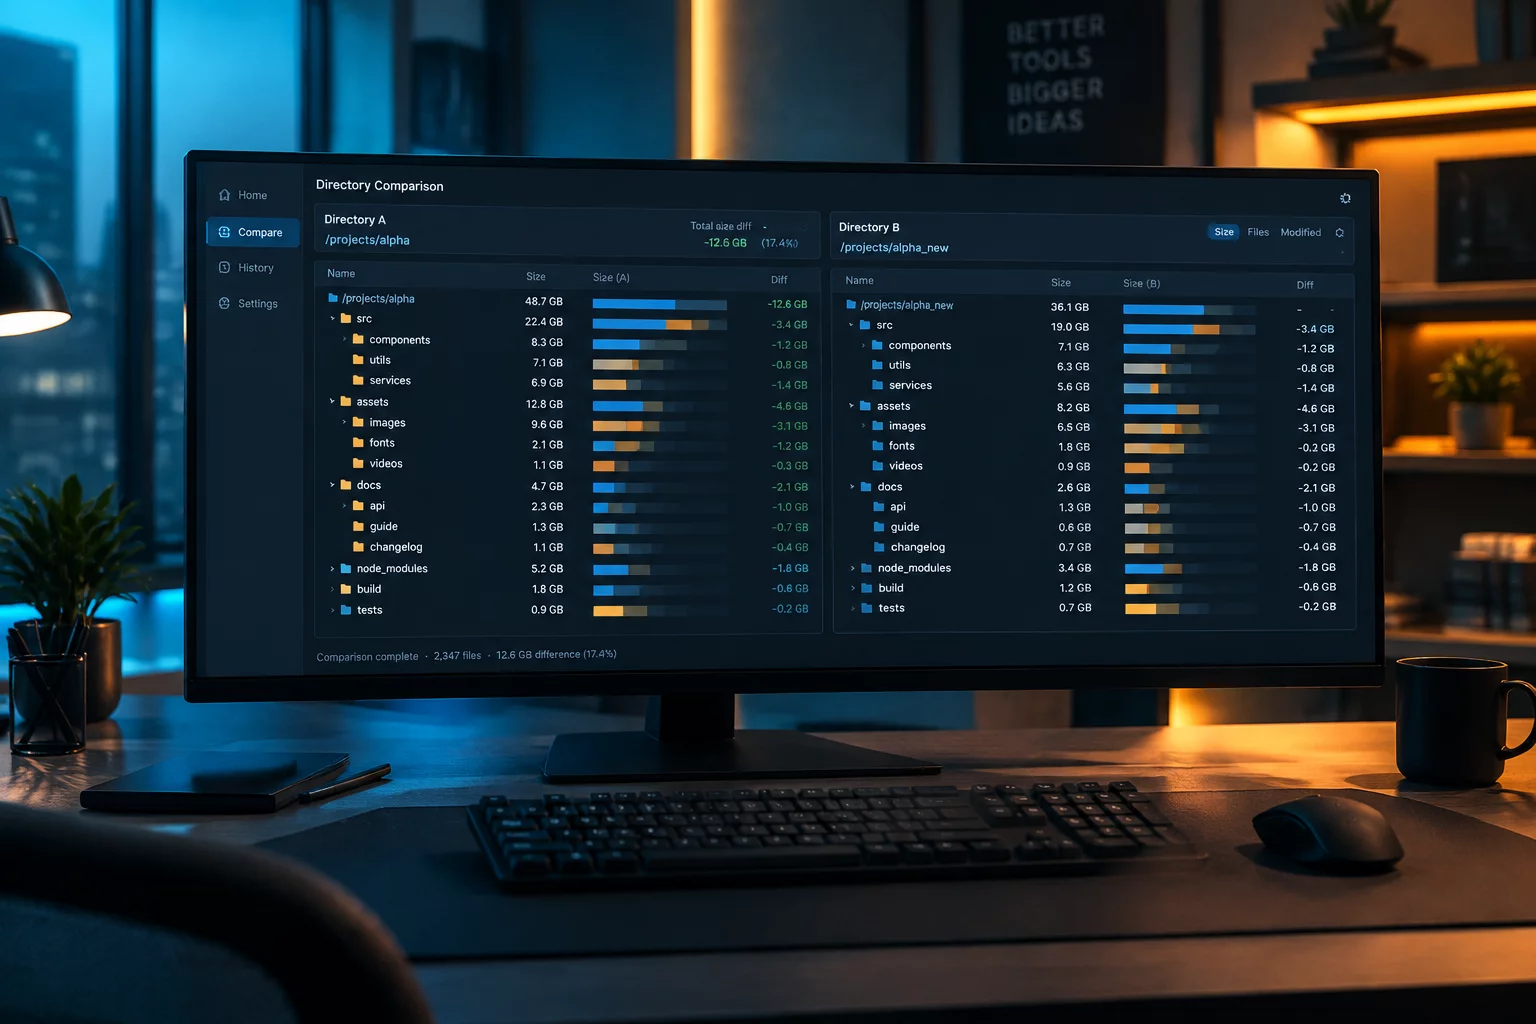
Compare recursive directory states side by side to pinpoint hidden binary bloat, orphaned build dumps, and uncompressed archives before archival commit.
Tracing Giant Binaries Through Comparative Snapshots
Differential examination of the Master File Table using WizTree exported snapshots exposed the mechanical shift. While developers successfully purged 38,400 miniature source scripts and vendor node files, the automated export scripts placed three colossal binary collections directly onto the staging volume without activating gzip or zstd streaming.
- Uncompressed Docker container filesystem archives (.tar) totaling 118.0 GB generated during automated integration runs and preserved in release packaging.
- Raw diagnostic SQL database seed exports totaling 49.0 GB created as migration safeguards but excluded from automated cleanup rules.
- Unstripped debugging symbol bundles (.pdb and .dSYM trees) amounting to 17.6 GB consolidated into the delivery root rather than remote debug stores.
Because the release manifest only logged top-level artifacts, the consolidation masked the exponential expansion of individual file weights. Consolidating thousands of files into uncompressed archive containers produced a rapid drop in file count alongside a devastating 59% rise in physical block consumption.
A 68% drop in directory file count creates a dangerous illusion of efficiency when monolithic tarballs and raw database dumps quietly devour hundreds of gigabytes underneath.
Analyzing the Shift from Granular Files to Heavy Monoliths
Evaluating storage metrics across checkpoint deltas proved that measuring storage health by file count alone is inherently flawed. When comparing the initial development snapshot against the final release candidate, the average object weight exploded by more than five hundred times.
Without low-level comparative tooling, an organization uploading this final tree to high-durability cold cloud tiers would incur long-term storage invoicing for raw database seeds and redundant container layers that serve zero runtime purpose.
Enforcing Automated Differential Threshold Gates
To eliminate this pattern permanently, the infrastructure team added an automated pre-delivery snapshot verification policy to continuous integration jobs. If a delivery snapshot demonstrates a decrease in overall file counts while simultaneously generating a net volume increase exceeding 10 GB, the build pipeline automatically halts release finalization. Seed databases now pass through high-ratio zstandard compression pipelines, container layers publish strictly to centralized container registries, and symbol packages relocate to symbol storage pools, reducing the final project archive from 497.0 GB down to an efficient 86.2 GB package.